<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://ruffyleaf.github.io/feed.xml" rel="self" type="application/atom+xml" /><link href="https://ruffyleaf.github.io/" rel="alternate" type="text/html" /><updated>2026-09-27T08:37:07+00:00</updated><id>https://ruffyleaf.github.io/feed.xml</id><title type="html">Maximilian Jackson</title><subtitle>Field notes from Maximilian Jackson — Director, Data &amp; AI — on turning data into decisions: practical data &amp; analytics, modern data systems and machine learning, and the leadership side of building data teams that ship.</subtitle><author><name>Maximilian Jackson</name></author><entry><title type="html">When a model earns its keep: anatomy of an ML project worth building</title><link href="https://ruffyleaf.github.io/data-analytics/ai/2026/09/26/when-a-model-earns-its-keep.html" rel="alternate" type="text/html" title="When a model earns its keep: anatomy of an ML project worth building" /><published>2026-09-26T15:15:00+00:00</published><updated>2026-09-26T15:15:00+00:00</updated><id>https://ruffyleaf.github.io/data-analytics/ai/2026/09/26/when-a-model-earns-its-keep</id><content type="html" xml:base="https://ruffyleaf.github.io/data-analytics/ai/2026/09/26/when-a-model-earns-its-keep.html"><![CDATA[<p>The last post was about when <em>not</em> to build a model — the three tests a request has to survive before modelling is even on the table. This one is the other side of the ledger: what a model looks like when it genuinely clears the bar, and worth every hour of maintenance it will quietly demand for years. Because they do exist. The point was never “fewer models.” The point is <em>models that earn their place</em>, and those have a recognisable shape if you know what to look for.</p>

<p>Here’s the anatomy, bottom to top — because the way a good model gets built is almost always the reverse of how it gets pitched.</p>

<h2 id="it-starts-from-a-decision-with-a-price-on-it">It starts from a decision with a price on it</h2>

<p>A model that earns its keep is anchored to one specific, expensive decision — and someone can tell you roughly what that decision is worth. Not “understand our customers better,” but “this forecast changes how much stock we hold, and being wrong costs us about X a quarter.” That dollar figure is the whole business case. It’s what you’ll measure the model against, what justifies the maintenance cost, and what tells you, honestly, when the model <em>isn’t</em> pulling its weight and should be retired.</p>

<p>If nobody can price the decision, it’s usually a curiosity project. Nothing wrong with that — but fund it as a prototype, not as production.</p>

<h2 id="the-signal-is-real-invisible-and-stable-ish">The signal is real, invisible, and stable-ish</h2>

<p>Three properties of the underlying pattern matter, and a worth-building model has all three:</p>

<p>The signal is <strong>real</strong> — there is genuinely more to know than the baseline already gives you. The embarrassing simple baseline (last value, the mean, the whiteboard rule) is <em>beatable by a meaningful margin</em>, not by a rounding error. If your fancy model beats the naïve forecast by a hair, it doesn’t clear the bar; the hair isn’t worth the machine.</p>

<p>The signal is <strong>invisible to a human</strong>. It lives in the interaction between dozens of features, or in a shape nobody could eyeball on a dashboard. This is the entire reason you reach for a model rather than a report — you’re finding structure that isn’t otherwise findable. If a domain expert could have written the rule, use their rule.</p>

<p>The signal is <strong>stable enough to survive shipping</strong>. Every model encodes an assumption about how the world works. When the world churns fast — a brand-new product with no history, a market mid-regime-change — that assumption rots before the model reaches production. A model earns its keep where the pattern has held long enough to learn <em>and</em> long enough to trust it next quarter.</p>

<h2 id="the-data-is-understood-not-just-available">The data is understood, not just available</h2>

<p>This is where my first post connects. A model is only as durable as your understanding of the data feeding it. A model worth building sits on a dataset you’ve actually profiled — you know its gaps, its sentinel values, its lineage, and which parts you’d bet a decision on. Fragile models are almost always a symptom of fragile data understanding: you built intelligence on top of something you never really inspected, and the model inherits every hidden flaw. When the data is understood, you can tell the difference between the model being clever and the model memorising a bug.</p>

<h2 id="theres-a-human-who-acts-differently-because-of-it">There’s a human who acts differently because of it</h2>

<p>A model earns its keep only if it changes what someone <em>does</em>. This is the most-skipped step and the biggest cause of abandoned ML. Before building, I want to see the shape of that change: where the output appears, in front of the person who acts, at the moment they’re about to act, in a form they trust enough to let it override their gut. A brilliant prediction buried in a report nobody opens is worth precisely nothing. The cheapest part of most successful model projects is the modelling; the expensive, decisive part is the last mile into a real workflow.</p>

<p>This is also why I care about <strong>explainability as a requirement, not a nicety</strong>. Not because stakeholders demand interpretability in the abstract, but because a person who acts on a model needs to sanity-check it. If the model says “deny this one” and can’t give a reason the operator respects, they’ll route around it — and now you’ve paid for a model you don’t actually use.</p>

<h2 id="the-maintenance-is-owned-from-day-one">The maintenance is owned, from day one</h2>

<p>Here’s the honesty test that separates teams that ship good models from teams with model graveyards: before you build, name who owns it in a year, and roughly what keeping it healthy costs. A model is a running commitment — pipelines that must keep feeding it, features that must stay available, drift that must be monitored, retraining that must happen when the world moves. If nobody’s budgeted for the boring forever-part, the model doesn’t earn its keep; it accrues a debt someone will pay later at high interest.</p>

<p>I like to write the model’s own “retirement criteria” down at the start: the conditions under which we’d knowingly switch it off. It forces the whole team to admit the model is a means to the priced decision from step one, not a thing that exists for its own sake.</p>

<h2 id="what-this-looks-like-in-the-wild">What this looks like in the wild</h2>

<p>Put together, a worthy model usually reads like: <em>a specific, priced decision; a signal that’s real, hidden, and reasonably stable; data we actually understand; a named human whose behaviour changes when the output appears; and an owned plan to keep it alive.</em> Miss any one of those and the model tends to be expensive theatre — accurate on the validation set, inert in the organisation.</p>

<p>When all of them line up, models are the best tool we have. They find what we can’t see, at a scale and speed no human matches, and they quietly compound value every day they run. That’s the version worth building. It’s just not the version most requests turn out to be — which is exactly the point of making them fight for their place.</p>

<p>Next, I want to zoom back out to the layer underneath all of this — <strong>making charts people actually trust</strong>: the small design and labeling choices that decide whether a non-specialist leans on a dashboard or quietly ignores it.</p>]]></content><author><name>Maximilian Jackson</name></author><category term="data-analytics" /><category term="ai" /><category term="machine-learning" /><category term="analytics" /><category term="decision-framework" /><category term="field-notes" /><summary type="html"><![CDATA[The last post was about when not to build a model — the three tests a request has to survive before modelling is even on the table. This one is the other side of the ledger: what a model looks like when it genuinely clears the bar, and worth every hour of maintenance it will quietly demand for years. Because they do exist. The point was never “fewer models.” The point is models that earn their place, and those have a recognisable shape if you know what to look for.]]></summary></entry><entry><title type="html">When NOT to build a model</title><link href="https://ruffyleaf.github.io/data-analytics/ai/2026/09/26/when-not-to-build-a-model.html" rel="alternate" type="text/html" title="When NOT to build a model" /><published>2026-09-26T14:45:00+00:00</published><updated>2026-09-26T14:45:00+00:00</updated><id>https://ruffyleaf.github.io/data-analytics/ai/2026/09/26/when-not-to-build-a-model</id><content type="html" xml:base="https://ruffyleaf.github.io/data-analytics/ai/2026/09/26/when-not-to-build-a-model.html"><![CDATA[<p>The fastest way to lose the plot on a data project is to start from the answer — <em>“let’s build a model for that”</em> — before anyone has said clearly what decision it’s supposed to improve. Machine learning has become the default ambition of far too many analytics requests, and the cost of that reflex is quietly enormous. Most problems asking for a model don’t need one. A well-built dashboard, a plain business rule, or even a genuinely cleaned dataset answers them better, faster, and in a way people actually trust.</p>

<p>This is the filter I run before I let anyone (including me) greenlight modelling work. It’s three questions, and a model has to survive all three to be worth building.</p>

<h2 id="test-1--can-you-state-the-decision-the-model-changes">Test 1 — Can you state the decision the model changes?</h2>

<p>Every model exists to make a specific decision better, cheaper, or faster. If you can’t name that decision in one sentence — <em>who</em> acts on the output, <em>what</em> they do differently, and <em>how</em> you’d know the world got better — you don’t have a modelling problem yet. You have a reporting problem, or a “we’re curious” problem. Both are legitimate, but neither deserves the expense of a production model. Curiosity is fine; just call it what it is and prototype it, don’t operationalise it.</p>

<p>A huge share of “AI requests” I’ve seen die right here. Someone wants a prediction, but the moment you trace it forward, the real need is a number on a screen that a human already knows how to interpret. That’s a SQL query and a chart, not a model. Ship those, and you’ve solved it this week instead of this quarter.</p>

<h2 id="test-2--is-the-pattern-already-obvious-to-the-people-in-the-room">Test 2 — Is the pattern already obvious to the people in the room?</h2>

<p>A model earns its keep when the signal is <strong>invisible to a human and expensive to get wrong</strong> — that’s the whole justification. When there are hundreds of interacting features, or the relationship genuinely shifts over time, modelling finds structure nobody could see by eye.</p>

<p>When there are only a handful of conditions, and a domain expert could write the rule on a whiteboard in ten minutes, a model is a liability. You’ve taken something transparent and made it opaque, slower, and harder to defend. The business user now has a <em>reason code</em> they can’t explain, an auditor has a black box they can’t sign off, and the moment the model does something odd, nobody can tell you why. A simple rule you can read, argue with, and change on a Tuesday afternoon is worth more than an accurate model you have to retrain and re-litigate. “Would a spreadsheet answer this?” is a surprisingly sharp question. If yes, it usually should.</p>

<h2 id="test-3--would-a-human-do-it-about-as-well-and-the-volume-is-low">Test 3 — Would a human do it about as well, and the volume is low?</h2>

<p>Even when a model <em>could</em> work, automation only pays off at volume. If a forecast is needed for thirty accounts and an analyst with a decent spreadsheet is 90% as good, the last 10% of accuracy is not worth the entire machine — the labelling, the pipeline, the monitoring, the drift. Automate what’s high-volume and repetitive. Leave the low-volume, high-judgment calls to humans and give them better tools and better data instead of a model.</p>

<h2 id="the-part-nobody-puts-in-the-pitch-deck">The part nobody puts in the pitch deck</h2>

<p>Models aren’t a build cost; they’re a <strong>maintenance cost that never stops</strong>. A model in production is an assumption about the world that quietly rots the day the world changes. Every one you ship is a recurring commitment: data pipelines that must keep feeding it, features that must stay available, thresholds that must be monitored, drift that must be detected and corrected, and a human who must own all of that when the original author has moved on. I’ve watched teams spend a quarter getting a model to work and then three years keeping it from falling over — for a problem a rules table would have covered on day one.</p>

<p>And there’s the trust cost. The moment a model gets a visible case wrong, the people you’re trying to help stop believing the whole thing, and you spend your credibility defending complexity instead of delivering clarity. A transparent rule that’s occasionally wrong in an <em>explainable</em> way holds trust far better than a slightly-more-accurate model that’s occasionally wrong in a <em>mysterious</em> way.</p>

<h2 id="what-earning-the-model-actually-looks-like">What “earning the model” actually looks like</h2>

<p>I’m not anti-model. I build them. But I want them to survive scrutiny, so I give them a fair trial:</p>

<ul>
  <li>A <strong>baseline</strong> that’s embarrassingly simple — often just the mean, or the rule the SME would write. If a gradient-boosted forest beats it by a rounding error, the model loses.</li>
  <li>A <strong>measure tied to the decision from Test 1</strong>, not an accuracy metric the business can’t feel. Precision on a chart is not the same as money saved or risk avoided.</li>
  <li>An honest <strong>total-cost estimate</strong>: build plus the maintenance forever, weighed against the value of that last sliver of improvement.</li>
</ul>

<p>Run that gauntlet and you’ll find models are occasionally, genuinely the right call — and when they clear it, everyone trusts them precisely <em>because</em> they had to fight for their place.</p>

<p>The mindset I’m pushing for is simple: treat a model as an expensive answer, not a default one. Most of good analytics is getting clean, well-understood data in front of a thoughtful human with a transparent view — and then only reaching for the model where the invisible-and-expensive condition truly holds. Fewer models, better models.</p>

<p>Next time I’ll take the other side of the ledger: the <strong>anatomy of a model that actually earned its keep</strong> — what made it worth every bit of the maintenance, start to finish.</p>]]></content><author><name>Maximilian Jackson</name></author><category term="data-analytics" /><category term="ai" /><category term="machine-learning" /><category term="analytics" /><category term="decision-framework" /><category term="field-notes" /><summary type="html"><![CDATA[The fastest way to lose the plot on a data project is to start from the answer — “let’s build a model for that” — before anyone has said clearly what decision it’s supposed to improve. Machine learning has become the default ambition of far too many analytics requests, and the cost of that reflex is quietly enormous. Most problems asking for a model don’t need one. A well-built dashboard, a plain business rule, or even a genuinely cleaned dataset answers them better, faster, and in a way people actually trust.]]></summary></entry><entry><title type="html">The dataset is never clean — a realistic first week on a messy dataset</title><link href="https://ruffyleaf.github.io/data-analytics/practice/2026/09/26/the-dataset-is-never-clean.html" rel="alternate" type="text/html" title="The dataset is never clean — a realistic first week on a messy dataset" /><published>2026-09-26T14:10:00+00:00</published><updated>2026-09-26T14:10:00+00:00</updated><id>https://ruffyleaf.github.io/data-analytics/practice/2026/09/26/the-dataset-is-never-clean</id><content type="html" xml:base="https://ruffyleaf.github.io/data-analytics/practice/2026/09/26/the-dataset-is-never-clean.html"><![CDATA[<p>If you work with data long enough, you hear the same request in a dozen different clothes: <em>“just clean the data and give me a dashboard.”</em> It sounds like a two-line task. It never is. The honest reality is that the dataset on your desk is already dirty in ways you can’t yet see, and the people asking for it don’t know which of those ways actually matter for the decision they’re trying to make. So the first week isn’t about cleaning anything. It’s about finding out <em>what kind of dirty</em> you’re dealing with, and which of it is safe to ignore.</p>

<p>Here’s the order I actually work in. Not the textbook order — the one that survives contact with real data.</p>

<h2 id="day-1--dont-touch-it-just-look">Day 1 — Don’t touch it. Just look.</h2>

<p>The instinct is to open the file and start fixing. Resist it for a day. On a large, unfamiliar dataset, the single most damaging thing you can do is change a value before you understand what the value <em>means</em>. So day one is pure profiling. I’m answering three questions:</p>

<ul>
  <li><strong>Shape.</strong> How many rows, how many columns, and does the row count match what the business expects? A table that’s supposed to hold every customer and somehow has fewer rows than there are active accounts is telling you something already.</li>
  <li><strong>Completeness.</strong> What share of each column is populated? Nulls aren’t uniformly bad — a column that’s 4% empty is a rounding error, a column that’s 60% empty is a story, and the story is almost never about the data.</li>
  <li><strong>Distributions.</strong> For every column that matters, look at its range and its shape. Min, max, mean, median, the obvious outliers. If a “age” column tops out at 147, or a monetary column is full of exact repeats down to the cent, or a date column has records from 1970, you’ve just found the seams where the dataset was stitched together.</li>
</ul>

<p>The output of day one isn’t a fix. It’s a list of surprises and a rough map of how bad it is.</p>

<h2 id="day-2--profile-like-a-detective-not-a-statistician">Day 2 — Profile like a detective, not a statistician</h2>

<p>The difference between an experienced data person and a script is that the script reports <em>what</em> is wrong; you need to work out <em>why</em>. Sentinel values masquerading as data are the classic example — a <code class="language-plaintext highlighter-rouge">-1</code> or <code class="language-plaintext highlighter-rouge">9999</code> or a blank string that isn’t really null but definitely isn’t a real value. A <code class="language-plaintext highlighter-rouge">GROUP BY</code> on the “weird” columns and a quick eyeball of the top and bottom values surfaces these fast.</p>

<p>Duplicate keys are the second category worth real time. Is a duplicate a genuine data-quality bug (the same transaction captured twice) or a modelling question (the same customer legitimately placing two orders)? You cannot know that from the data alone, which is the segue into day three.</p>

<h2 id="day-3--follow-the-lineage-before-you-follow-your-gut">Day 3 — Follow the lineage before you follow your gut</h2>

<p>Most “cleaning” mistakes are really lineage mistakes. Before I dedupe, impute, or standardise anything, I want to know where each field <em>comes from</em>. Which upstream system owns it. Whether it’s a daily snapshot or an append-only log. Who else downstream already depends on it.</p>

<p>This matters because the same field often means different things in different systems, and a value that looks broken in isolation is perfectly correct given how it was produced. A null that’s genuinely “missing” and a null that means “the user skipped an optional field” look identical in the file and require opposite treatments. You only tell them apart by walking the data back to its source and asking the people who own it a small number of specific questions.</p>

<p>The other reason to do lineage early: once you know what downstream systems read this data, you also know what you’re <em>not</em> allowed to change casually. That constraint shapes every decision after it.</p>

<h2 id="day-4--fix-the-unambiguous-things-in-the-open">Day 4 — Fix the unambiguous things, in the open</h2>

<p>Now you’re allowed to fix something — but only the changes that are clearly right and cheap to reverse. Standardising formats (dates to one format, text to one case, units to one system). Collapsing obvious sentinel values into true nulls. Documenting every one of them in a single, boring, readable log that says <em>what you changed, why, and how to undo it.</em></p>

<p>That log is the difference between a data professional and a person who quietly breaks a report. Nobody ever resents a well-documented change. They resent finding out three weeks later that the numbers moved and no one can say why.</p>

<h2 id="day-5--handle-the-judgment-calls-as-decisions-not-accidents">Day 5 — Handle the judgment calls as decisions, not accidents</h2>

<p>The genuinely hard problems don’t have a “correct” answer; they have a defensible one you chose on purpose. Do you impute the missing values, drop the rows, or leave the gap visible and let the consumer decide? Do you merge two records that are <em>probably</em> the same person, or keep them separate and accept the overcount? Each of these should be written down as a small, explicit decision with a rationale and a home (usually the same log), so that six months later you can explain the shape of the data to someone who wasn’t in the room.</p>

<p>A good rule I use: make the choice that a reasonable colleague, reading only the dashboard and not the code, would find least misleading. Data engineering optimises for correctness; decision support optimises for trust. On a messy dataset you’re doing both jobs at once.</p>

<h2 id="the-checklist-i-keep">The checklist I keep</h2>

<p>Stripped down, the first-week sequence is:</p>

<ol>
  <li>Row counts and key uniqueness against what the business expects.</li>
  <li>Null / empty rate for every column.</li>
  <li>Range and distribution for every column that feeds a decision.</li>
  <li>Hunt for sentinel values and impossible dates.</li>
  <li>Write a “what I’d expect vs. what I see” list.</li>
  <li>Map each field to its source system and its downstream users.</li>
  <li>Fix only the reversible, unambiguous problems — and log every one.</li>
  <li>Turn the remaining mess into explicit, documented decisions.</li>
</ol>

<p>The point of the whole week isn’t to arrive at a clean dataset. It’s to arrive at a dataset you <em>understand</em> — one where you know exactly which parts are trustworthy, which parts are a judgment call, and which parts you’d never bet a decision on. That’s the honest version of “clean,” and it’s the only kind that actually holds up when someone asks you, a month later, <em>“can we rely on this?”</em></p>

<p>Next time, I’ll go the other way on purpose: <strong>when NOT to build a model</strong> — the framework I use for spotting when a simple dashboard or a plain rule earns its keep better than machine learning ever could.</p>]]></content><author><name>Maximilian Jackson</name></author><category term="data-analytics" /><category term="practice" /><category term="data-quality" /><category term="analytics" /><category term="data-management" /><category term="field-notes" /><summary type="html"><![CDATA[If you work with data long enough, you hear the same request in a dozen different clothes: “just clean the data and give me a dashboard.” It sounds like a two-line task. It never is. The honest reality is that the dataset on your desk is already dirty in ways you can’t yet see, and the people asking for it don’t know which of those ways actually matter for the decision they’re trying to make. So the first week isn’t about cleaning anything. It’s about finding out what kind of dirty you’re dealing with, and which of it is safe to ignore.]]></summary></entry><entry><title type="html">Hello, I’m Maximilian</title><link href="https://ruffyleaf.github.io/personal/introduction/data-ai/2026/09/26/hello-im-maximilian.html" rel="alternate" type="text/html" title="Hello, I’m Maximilian" /><published>2026-09-26T13:15:58+00:00</published><updated>2026-09-26T13:15:58+00:00</updated><id>https://ruffyleaf.github.io/personal/introduction/data-ai/2026/09/26/hello-im-maximilian</id><content type="html" xml:base="https://ruffyleaf.github.io/personal/introduction/data-ai/2026/09/26/hello-im-maximilian.html"><![CDATA[<p>This is the first post on my new blog, so it seems only fair to start with a quick introduction.</p>

<p>I’m <strong>Maximilian Jackson</strong>. I’ve spent the last twenty years working with data inside technology organisations — helping them take large, messy, complicated datasets and turn them into information people can actually make decisions with. My work has gradually moved from statistics and modelling into the broader world of data management, analytics, and AI leadership.</p>

<p>Right now I’m <strong>Director, Data &amp; AI at B H S</strong>, doing some of the most hands-on work I’ve had in years. I’m organising the data, rebuilding the systems that sit on top of it, redesigning the processes and the jobs that depend on those systems, and training the people who use all of it every day. It’s equal parts setting strategy and getting things to actually work in practice.</p>

<p>At the core of what I do is a simple obsession: converting data into clarity. That spans the whole lifecycle — integration and management, then modelling with machine learning, advanced statistics, custom algorithms, network graphs, and operations research, and finally visualisation and dashboards that non-specialists can genuinely read and trust. I care just as much about the human side: translating between technical teams and business stakeholders, and building and leading teams that ship good work.</p>

<p>You can expect posts here about a few recurring themes:</p>

<ul>
  <li><strong>Data &amp; analytics in practice</strong> — how you take a large, complicated dataset and shape it into something that actually improves a decision.</li>
  <li><strong>AI and modern data systems</strong> — rebuilding data estates, and where machine learning and advanced modelling earn their keep (and where they don’t).</li>
  <li><strong>Leadership and enablement</strong> — stakeholder management, team building, and training people to work confidently with data.</li>
</ul>

<p>I started this blog as a place to think out loud and document lessons from the field — especially while I’m mid-rebuild at B H S. This is the messy, real version of the work that doesn’t fit neatly into a slide deck.</p>

<p>I don’t have a rigid schedule. The plan is to write when I have something worth sharing and keep it useful.</p>

<p>If you’d like to reach me or see more of my work, find my code on <a href="https://github.com/ruffyleaf">GitHub</a> or connect with me on <a href="https://www.linkedin.com/in/mjyzc/">LinkedIn</a>.</p>

<p>Thanks for reading — more soon.</p>]]></content><author><name>Maximilian Jackson</name></author><category term="personal" /><category term="introduction" /><category term="data-ai" /><category term="hello" /><category term="introduction" /><category term="data-analytics" /><category term="leadership" /><summary type="html"><![CDATA[This is the first post on my new blog, so it seems only fair to start with a quick introduction.]]></summary></entry><entry><title type="html">Lakehouse Essentials: building a Databricks medallion stack as a one-person data team</title><link href="https://ruffyleaf.github.io/data-engineering/2025/01/04/lakehouse-essentials.html" rel="alternate" type="text/html" title="Lakehouse Essentials: building a Databricks medallion stack as a one-person data team" /><published>2025-01-04T08:03:00+00:00</published><updated>2025-01-04T08:03:00+00:00</updated><id>https://ruffyleaf.github.io/data-engineering/2025/01/04/lakehouse-essentials</id><content type="html" xml:base="https://ruffyleaf.github.io/data-engineering/2025/01/04/lakehouse-essentials.html"><![CDATA[<p>Building a lakehouse sounds like a daunting engineering task. It’s a phrase that summons images of a full platform team, months of infrastructure yak-shaving, and a budget line that makes finance wince. I wanted to write up the fundamental components I actually used to build a lakehouse on Databricks at GetGo — and along the way show that, for a single-person data operation, it’s genuinely more tractable than the marketing suggests. The reason is simple: Databricks bundles most of the hard parts out of the box, so one person can spend their time on <em>data processing</em> rather than <em>infrastructure</em>. You’ll soon see that it’s really easy. Let’s go.</p>

<p><em>(A note on dating: this is written up as it stood in early 2025. It reflects the tooling and the one-team context at GetGo at the time, and some of it — especially the platform speculation — has already moved on. Read it as field notes from a specific moment, not a current-state reference.)</em></p>

<p>The whole thing comes down to three sections: <strong>ETL</strong>, <strong>Delta Lake</strong>, and <strong>Orchestration</strong>.</p>

<h2 id="the-shape-of-the-thing-medallion-architecture">The shape of the thing: medallion architecture</h2>

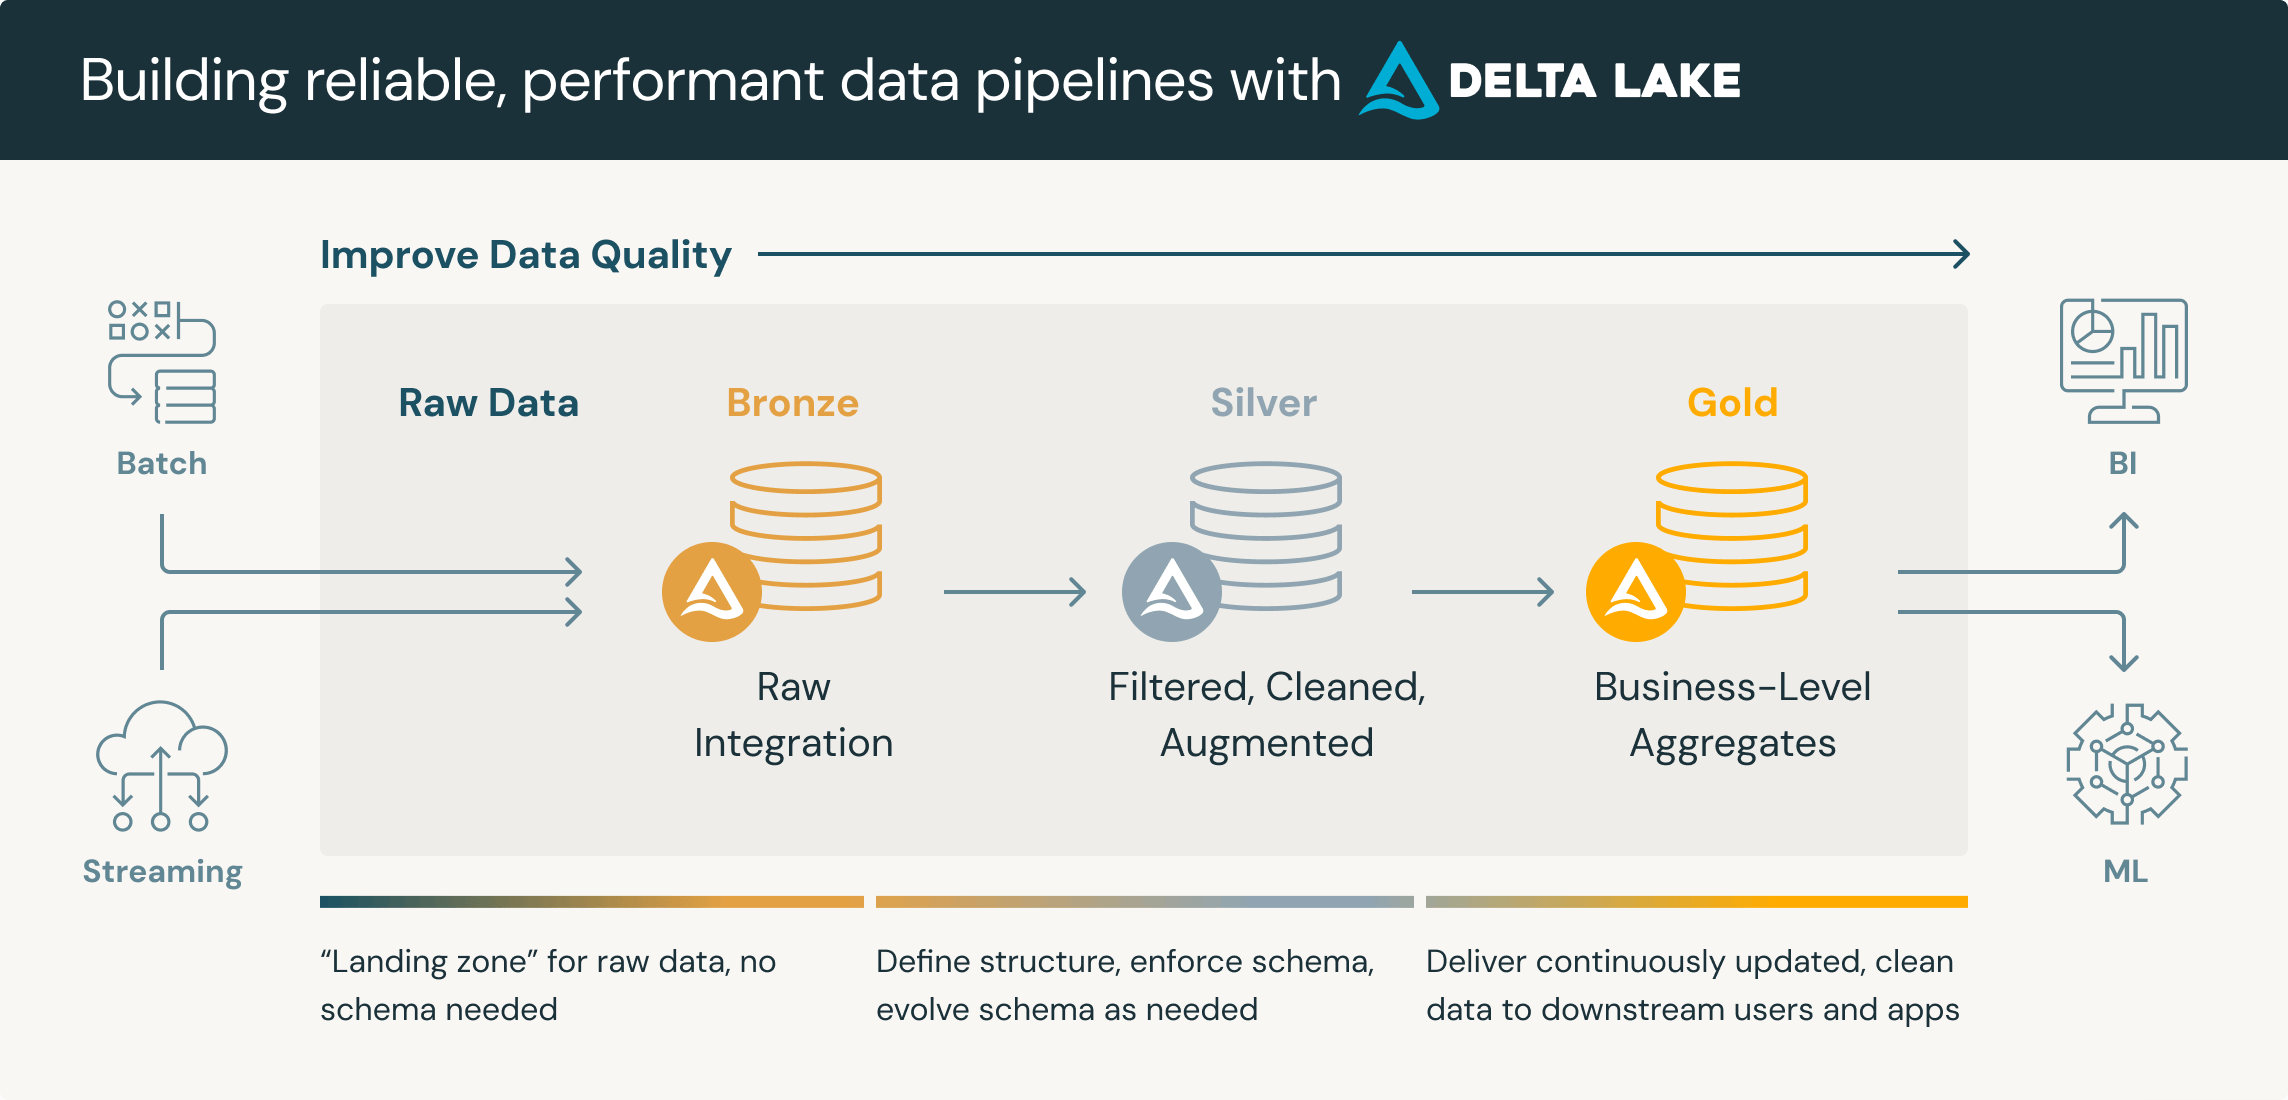
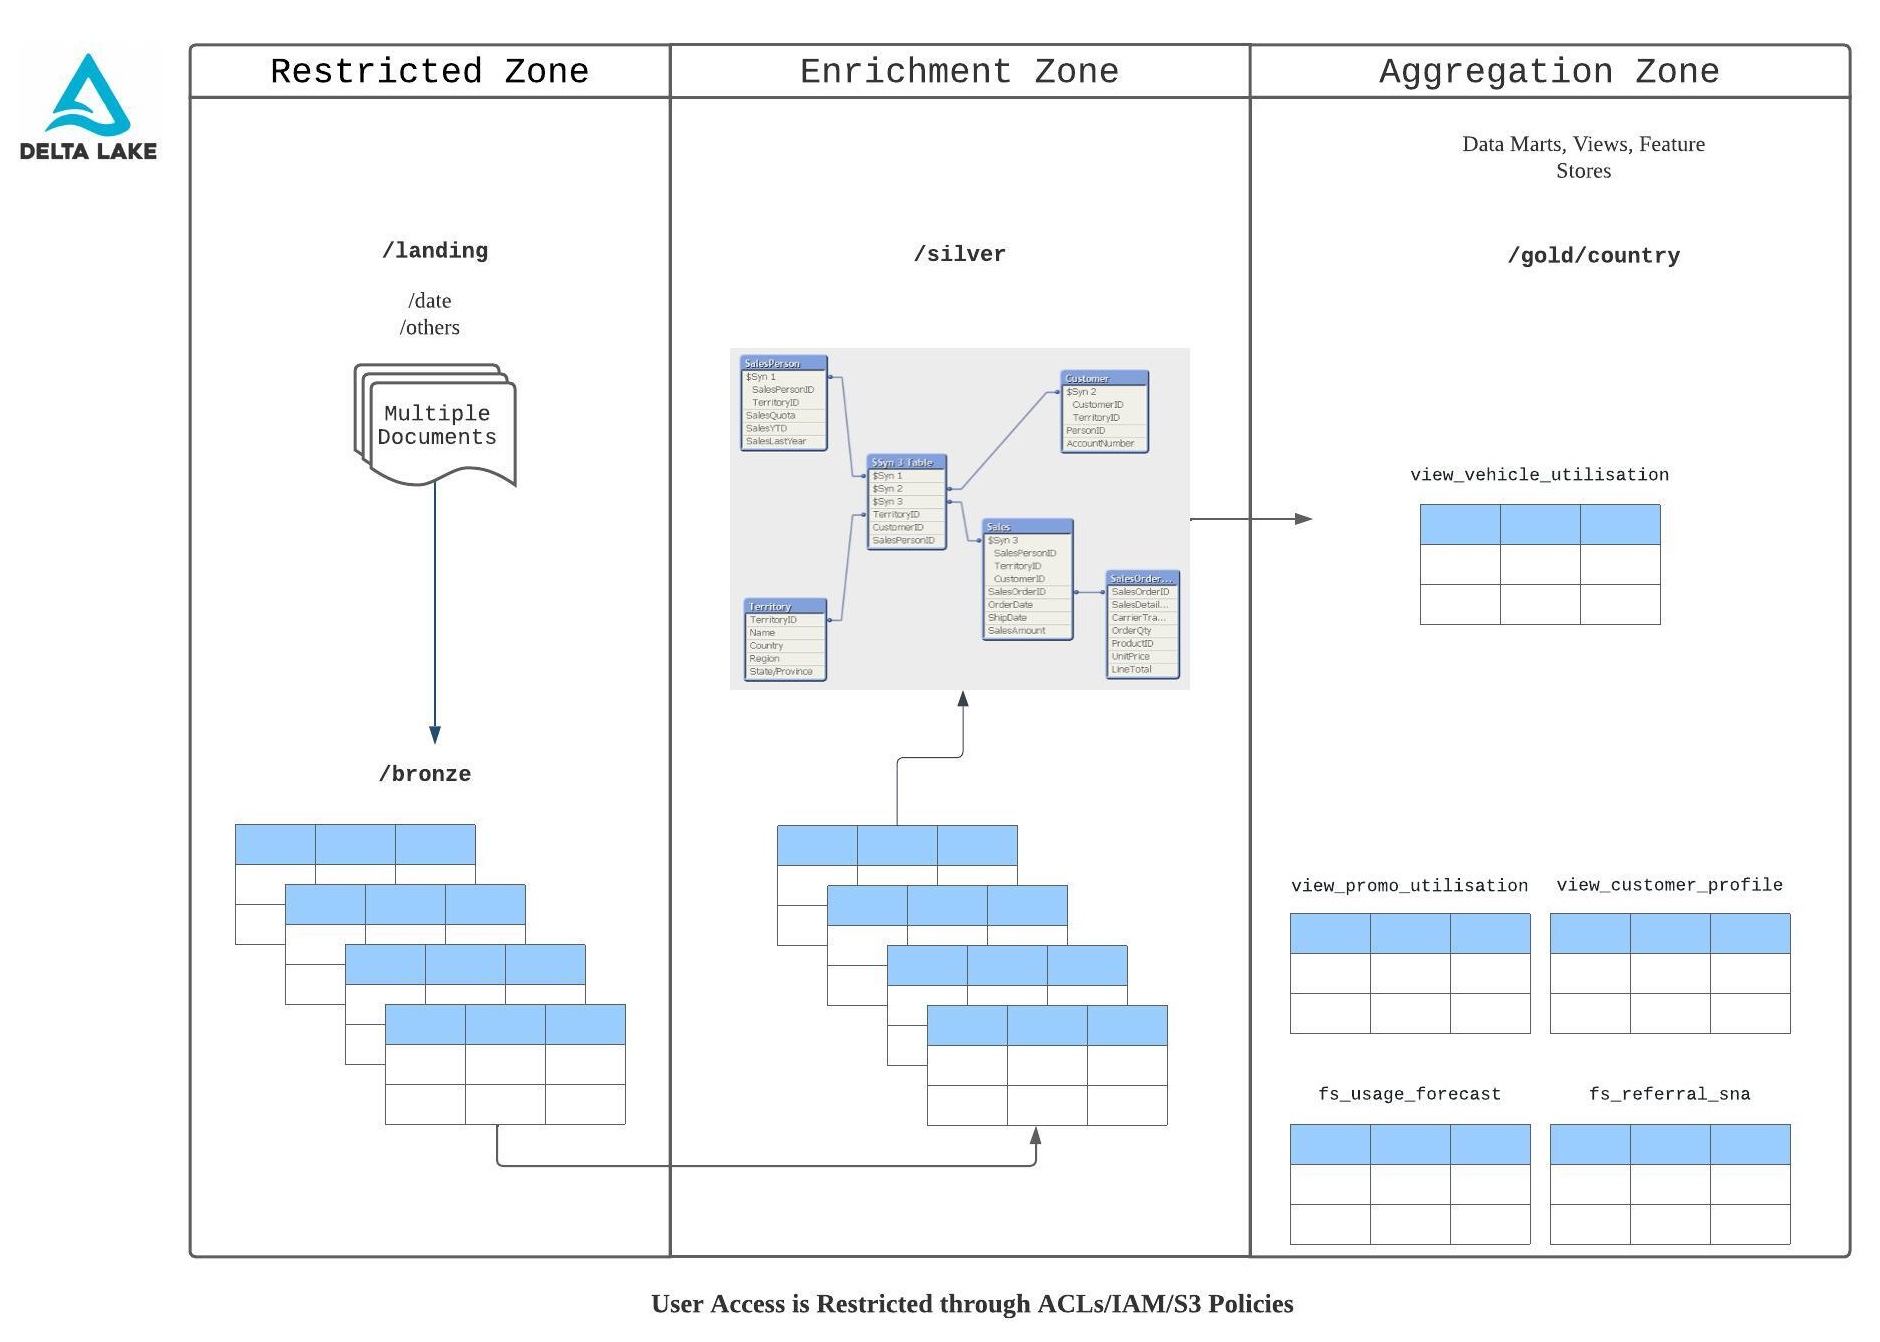
<p>At a high level, we build the lakehouse on Delta Lake, and organise it into three “zones”:</p>

<ul>
  <li>a <strong>raw zone</strong> for landing and processing incoming files,</li>
  <li>an <strong>enrichment zone</strong> that extracts transactional data, cleans it, and stores it as facts and dimensions,</li>
  <li>an <strong>aggregation zone</strong> that builds business-level summaries.</li>
</ul>

<p>This is the <em>medallion architecture</em> — <strong>Bronze</strong>, <strong>Silver</strong>, <strong>Gold</strong> — named so the tiers are easy to refer to and reason about. Bronze is raw and trusting of nothing; Silver is clean, typed, and business-shaped; Gold is aggregated and ready for a dashboard.</p>

<figure>
  <img src="/assets/images/medallion-architecture.png" alt="Medallion architecture: batch and streaming raw data flow through Bronze (raw integration), Silver (filtered, cleaned, augmented) and Gold (business-level aggregates) before feeding BI and ML" />
  <figcaption>Medallion architecture — the Bronze, Silver and Gold tiers.</figcaption>
</figure>

<figure>
  <img src="/assets/images/lakehouse-zones.jpeg" alt="Lakehouse zones: a Restricted Zone holding the landing and bronze layers, an Enrichment Zone holding silver, and an Aggregation Zone holding gold views and feature stores, with user access restricted through ACLs, IAM and S3 policies" />
  <figcaption>The three lakehouse zones, and how access is fenced off between them.</figcaption>
</figure>

<p>The unified platform is what makes the one-person version viable. Out-of-the-box features — streaming ingestion, incremental change tracking, ACID tables, a built-in scheduler — amplify what a single data engineer can carry.</p>

<h2 id="etl">ETL</h2>

<h3 id="data-ingestion">Data ingestion</h3>

<p>The first step is ingestion: think of it as continually producing files of <em>incremental</em> data that need to be processed and stored in the warehouse. Those files get generated and dropped into cloud object storage, and from there the lakehouse takes over.</p>

<p>This is probably the hardest and most uncertain part of the whole lakehouse. Data comes from everywhere — email, relational databases, SFTP, documents, accounting software, CRMs, Excel sheets, customer chat platforms, REST APIs, server logs, social media, marketing platforms. The list genuinely goes on. Assuming each source maps to a validated business use case, our job as data engineers is to pipe it in, and the sky’s the limit on how.</p>

<p>Roughly, the toolbox splits into scripts and products:</p>

<p><strong>Scripts</strong></p>

<ul>
  <li>Python on serverless (AWS Lambda, Azure Functions) or on servers — good for SFTP, social media, and REST APIs</li>
  <li>Google Apps Script — handy for email attachments when your mailbox is Gmail</li>
  <li>SQLAlchemy</li>
</ul>

<p><strong>Products</strong></p>

<ul>
  <li>Fivetran, Airbyte, Stitch, Power Automate, AWS Database Migration Service, Estuary, Informatica</li>
</ul>

<p>The capability of each product, and the combinations of script-and-product you can pull off, are endless. In the end it reduces to a function of <strong>cost</strong> and the <strong>environment you operate in</strong>. If you’re not on Gmail, for example, you’ll need an email connector (Fivetran, Airbyte) or you’ll stand up AWS Simple Email Service to save attachments into S3 — and that S3 bucket should sit in a sanitisation zone so anti-virus can scan files before they ever reach the lakehouse.</p>

<p>For the mechanical SFTP→S3 problem, I have an older step-by-step that pairs the AWS CLI, a Makefile, and Python to move files into object storage. I wrote it in 2017 and it was still working in 2024 — a small testament to how boring and reliable the right ingestion plumbing should be.</p>

<h3 id="relational-databases">Relational databases</h3>

<p>For databases, I’ve used <strong>Fivetran</strong> and <strong>AWS DMS</strong> to perform Change Data Capture (CDC). They behave differently in a way that matters:</p>

<ul>
  <li><strong>Fivetran</strong> ships <em>Teleport Sync</em>, which pulls deltas <em>without</em> requiring you to enable binary logging on the source database.</li>
  <li><strong>AWS DMS</strong> relies on the <em>bin log</em> to identify changes. The bin log degrades database performance from an IOPS perspective, but in our case the pros outweighed the cons.</li>
</ul>

<p>A platform-specific wrinkle: Fivetran can push straight into your Bronze tables, whereas AWS DMS drops CSV/Parquet into a landing S3 bucket that then needs processing <em>into</em> Bronze. One integration point of friction, saved.</p>

<p>Databricks had also just acquired Arcion, a CDC specialist, and with Unity Catalog leaning on Lakehouse Federation, my then-hope was that native CDC replication into the lakehouse would become table stakes and pull ingestion inside the platform. Time will tell on that one.</p>

<h2 id="data-processing">Data processing</h2>

<h3 id="bronze--the-raw--ingestion-zone">Bronze — the raw / ingestion zone</h3>

<p>Files are now sitting in object storage. Autoloader does exactly what its name says: it automatically reads <em>new</em> files as they land, using Spark Streaming, and keeps a log of which files have already been ingested so the incremental pattern is reliable. New arrivals are picked up and loaded into a streaming DataFrame ready for processing.</p>

<p>For each source we keep two notebooks: one to <strong>initialise</strong> the Bronze table from everything currently in object storage, and one to process the <strong>incrementals</strong> (deltas). The init notebook just reads all the files that exist today and forms the initial raw table.</p>

<p>One deliberate choice when creating Bronze: <strong>cast every column to String.</strong> You’re not fighting messy type inference at ingestion; you’re just forming a structured table so cleaning can proceed. Real types come later, in Silver.</p>

<p>Once the Bronze table exists, it’s ready to take deltas via Autoloader. Reading a new batch into a Spark DataFrame:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">bronze_booking_concluded_df</span> <span class="o">=</span> <span class="p">(</span>
    <span class="n">spark</span><span class="p">.</span><span class="n">readStream</span>
    <span class="p">.</span><span class="nb">format</span><span class="p">(</span><span class="s">'cloudFiles'</span><span class="p">)</span>
    <span class="p">.</span><span class="n">option</span><span class="p">(</span><span class="s">'cloudFiles.format'</span><span class="p">,</span> <span class="s">'csv'</span><span class="p">)</span>
    <span class="p">.</span><span class="n">option</span><span class="p">(</span><span class="s">'header'</span><span class="p">,</span> <span class="s">'true'</span><span class="p">)</span>
    <span class="p">.</span><span class="n">option</span><span class="p">(</span><span class="s">'inferSchema'</span><span class="p">,</span> <span class="s">'true'</span><span class="p">)</span>
    <span class="p">.</span><span class="n">option</span><span class="p">(</span><span class="s">'cloudFiles.schemaLocation'</span><span class="p">,</span> <span class="n">schema_path</span><span class="p">)</span>
    <span class="p">.</span><span class="n">option</span><span class="p">(</span><span class="s">'rescuedDataColumn'</span><span class="p">,</span> <span class="s">'_rescue'</span><span class="p">)</span>
    <span class="p">.</span><span class="n">load</span><span class="p">(</span><span class="n">input_table_path</span><span class="p">)</span>
<span class="p">)</span>
</code></pre></div></div>

<p>New files are picked up at the next scheduled run. If a source adds <em>new columns</em> you didn’t plan for, Autoloader doesn’t blow up — the surprises land in a <code class="language-plaintext highlighter-rouge">_rescue</code> column as JSON, so the pipeline keeps flowing while you decide what the new field means. Then you append into the Bronze table:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">(</span>
    <span class="n">bronze_booking_concluded_df</span>
    <span class="p">.</span><span class="n">writeStream</span>
    <span class="p">.</span><span class="nb">format</span><span class="p">(</span><span class="s">'delta'</span><span class="p">)</span>
    <span class="p">.</span><span class="n">trigger</span><span class="p">(</span><span class="n">availableNow</span><span class="o">=</span><span class="bp">True</span><span class="p">)</span>
    <span class="p">.</span><span class="n">option</span><span class="p">(</span><span class="s">'mergeSchema'</span><span class="p">,</span> <span class="s">'true'</span><span class="p">)</span>
    <span class="p">.</span><span class="n">option</span><span class="p">(</span><span class="s">'checkpointLocation'</span><span class="p">,</span> <span class="n">checkpoint_path</span><span class="p">)</span>
    <span class="p">.</span><span class="n">outputMode</span><span class="p">(</span><span class="s">'append'</span><span class="p">)</span>
    <span class="p">.</span><span class="n">start</span><span class="p">(</span><span class="n">output_table_path</span><span class="p">)</span>
    <span class="p">.</span><span class="n">awaitTermination</span><span class="p">()</span>
<span class="p">)</span>
</code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">availableNow=True</code> is the key operational trick: it processes all currently-available data and then <em>exits</em>, instead of running forever. That lets you schedule the Delta notebook as a batch job at fixed times. If you truly want continuous ingestion, you leave a cluster running 24/7 and drop the bounded trigger.</p>

<h3 id="silver--the-enrichment-zone">Silver — the enrichment zone</h3>

<p>Silver tables are built from Bronze, and again each gets an <em>init</em> and a <em>delta</em> notebook. The init reads Bronze wholesale, but this time selects only the columns you want and casts them into <strong>proper types</strong> — strings become dates, integers, and so on — and removes duplicates. This is where raw text becomes trustworthy data.</p>

<p>The delta notebooks lean on Spark Streaming plus Delta Lake’s <strong>Change Data Feed</strong> to process only what’s changed since the last known point. (Practical note: don’t use Databricks’ own docs for CDF — go to the Delta Lake docs, they’re clearer and have better examples.)</p>

<p>Concretely, ingesting from a Bronze table created by AWS DMS CDC. <code class="language-plaintext highlighter-rouge">upsertToDelta</code> is the micro-batch function Spark Streaming calls to apply the deltas — “upsert” being Update/Insert/Merge in one, which is one of the genuinely nice Delta features. Without it you’d stage the incremental data in a temp table and then merge the staging table into the target by hand.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">def</span> <span class="nf">upsertToDelta</span><span class="p">(</span><span class="n">microBatchOutputDF</span><span class="p">,</span> <span class="n">batchId</span><span class="p">):</span>
    <span class="p">(</span>
        <span class="n">delta_table</span><span class="p">.</span><span class="n">alias</span><span class="p">(</span><span class="s">"target"</span><span class="p">)</span>
        <span class="p">.</span><span class="n">merge</span><span class="p">(</span>
            <span class="p">(</span>
                <span class="n">microBatchOutputDF</span>
                <span class="p">.</span><span class="nb">filter</span><span class="p">(</span><span class="n">col</span><span class="p">(</span><span class="s">'Op'</span><span class="p">).</span><span class="n">isin</span><span class="p">([</span><span class="s">'I'</span><span class="p">,</span> <span class="s">'U'</span><span class="p">]))</span>
                <span class="p">.</span><span class="n">withColumn</span><span class="p">(</span>
                    <span class="s">'rnk'</span><span class="p">,</span>
                    <span class="n">rank</span><span class="p">().</span><span class="n">over</span><span class="p">(</span>
                        <span class="n">Window</span><span class="p">.</span><span class="n">partitionBy</span><span class="p">(</span><span class="sa">f</span><span class="s">'</span><span class="si">{</span><span class="n">join_key</span><span class="si">}</span><span class="s">'</span><span class="p">)</span>
                              <span class="p">.</span><span class="n">orderBy</span><span class="p">(</span><span class="n">col</span><span class="p">(</span><span class="s">'transact_id'</span><span class="p">).</span><span class="n">desc</span><span class="p">())</span>
                    <span class="p">)</span>
                <span class="p">)</span>
                <span class="p">.</span><span class="nb">filter</span><span class="p">(</span><span class="n">col</span><span class="p">(</span><span class="s">'rnk'</span><span class="p">)</span> <span class="o">==</span> <span class="mi">1</span><span class="p">)</span>
                <span class="p">.</span><span class="n">drop</span><span class="p">(</span><span class="s">'rnk'</span><span class="p">)</span>
                <span class="p">.</span><span class="n">dropDuplicates</span><span class="p">()</span>
            <span class="p">).</span><span class="n">alias</span><span class="p">(</span><span class="s">'source'</span><span class="p">),</span>
            <span class="sa">f</span><span class="s">'source.</span><span class="si">{</span><span class="n">join_key</span><span class="si">}</span><span class="s"> = target.</span><span class="si">{</span><span class="n">join_key</span><span class="si">}</span><span class="s">'</span>
        <span class="p">)</span>
        <span class="p">.</span><span class="n">whenMatchedUpdateAll</span><span class="p">(</span><span class="n">condition</span><span class="o">=</span><span class="n">update_condition</span><span class="p">)</span>
        <span class="p">.</span><span class="n">whenNotMatchedInsertAll</span><span class="p">()</span>
        <span class="p">.</span><span class="n">execute</span><span class="p">()</span>
    <span class="p">)</span>

<span class="p">(</span>
    <span class="n">silver_booking_concluded_delta_df</span>
    <span class="p">.</span><span class="n">writeStream</span>
    <span class="p">.</span><span class="nb">format</span><span class="p">(</span><span class="s">'delta'</span><span class="p">)</span>
    <span class="p">.</span><span class="n">foreachBatch</span><span class="p">(</span><span class="n">upsertToDelta</span><span class="p">)</span>
    <span class="p">.</span><span class="n">outputMode</span><span class="p">(</span><span class="s">'update'</span><span class="p">)</span>
    <span class="p">.</span><span class="n">trigger</span><span class="p">(</span><span class="n">availableNow</span><span class="o">=</span><span class="bp">True</span><span class="p">)</span>
    <span class="p">.</span><span class="n">start</span><span class="p">()</span>
    <span class="p">.</span><span class="n">awaitTermination</span><span class="p">()</span>
<span class="p">)</span>
</code></pre></div></div>

<p>Why all the <code class="language-plaintext highlighter-rouge">Window</code> / <code class="language-plaintext highlighter-rouge">rank()</code> ceremony? Because plain <code class="language-plaintext highlighter-rouge">dropDuplicates()</code> in Spark doesn’t keep the latest or earliest row — it drops duplicates <em>arbitrarily</em>. If a key arrives several times in a micro-batch, you want to deterministically keep the newest one by <code class="language-plaintext highlighter-rouge">transact_id</code>, so you rank within the partition and keep rank 1. It’s the difference between “mostly correct” and “defensible at 2am when someone asks why the numbers moved.”</p>

<p>If the data genuinely doesn’t care about row order, you can skip the windowing and keep it simple:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">def</span> <span class="nf">upsertToDelta</span><span class="p">(</span><span class="n">microBatchOutputDF</span><span class="p">,</span> <span class="n">batchId</span><span class="p">):</span>
    <span class="p">(</span>
        <span class="n">delta_table</span><span class="p">.</span><span class="n">alias</span><span class="p">(</span><span class="s">'t'</span><span class="p">)</span>
        <span class="p">.</span><span class="n">merge</span><span class="p">(</span>
            <span class="n">microBatchOutputDF</span><span class="p">.</span><span class="n">dropDuplicates</span><span class="p">([</span><span class="n">join_key</span><span class="p">]).</span><span class="n">alias</span><span class="p">(</span><span class="s">'s'</span><span class="p">),</span>
            <span class="sa">f</span><span class="s">'s.</span><span class="si">{</span><span class="n">join_key</span><span class="si">}</span><span class="s"> = t.</span><span class="si">{</span><span class="n">join_key</span><span class="si">}</span><span class="s">'</span>
        <span class="p">)</span>
        <span class="p">.</span><span class="n">whenMatchedUpdateAll</span><span class="p">()</span>
        <span class="p">.</span><span class="n">whenNotMatchedInsertAll</span><span class="p">()</span>
        <span class="p">.</span><span class="n">execute</span><span class="p">()</span>
    <span class="p">)</span>

<span class="p">(</span>
    <span class="n">fact_c_delta_df</span>
    <span class="p">.</span><span class="n">writeStream</span>
    <span class="p">.</span><span class="nb">format</span><span class="p">(</span><span class="s">'delta'</span><span class="p">)</span>
    <span class="p">.</span><span class="n">foreachBatch</span><span class="p">(</span><span class="n">upsertToDelta</span><span class="p">)</span>
    <span class="p">.</span><span class="n">outputMode</span><span class="p">(</span><span class="s">'update'</span><span class="p">)</span>
    <span class="p">.</span><span class="n">trigger</span><span class="p">(</span><span class="n">availableNow</span><span class="o">=</span><span class="bp">True</span><span class="p">)</span>
    <span class="p">.</span><span class="n">start</span><span class="p">()</span>
    <span class="p">.</span><span class="n">awaitTermination</span><span class="p">()</span>
<span class="p">)</span>
</code></pre></div></div>

<h3 id="silver--fact-and-dimension-tables">Silver — fact and dimension tables</h3>

<p>The whole point of the warehouse is to make information easy to analyse. Transactional databases aren’t built for that: they’re heavily <em>normalised</em> to preserve data integrity, which is great for OLTP and miserable for analytics. Fact and dimension tables are <em>de-normalised</em> — shaped for aggregation and, ultimately, dashboards that answer real business questions. This master data also preserves the business context that downstream teams rely on.</p>

<p>A few principles that keep the semantic layer humane:</p>

<ul>
  <li>Enrich with data from outside the transactional system — weather, for instance — to widen the range of questions the model can answer.</li>
  <li>Replace numeric category references with the category <em>names</em>, so you shed unnecessary joins.</li>
  <li>Keep infrequently-used reference data separate and join it only when needed.</li>
</ul>

<p>Each fact and dimension table gets its own init and delta notebooks, same as everything else. We also keep <strong>quarantine tables</strong> for records that fail quality or integrity checks. The value is that a workflow can continue running while bad rows are isolated and fixed before re-introduction — at the cost of an extra daily check that the quarantine batches are actually being worked.</p>

<p>The classic enrichment dimension is <code class="language-plaintext highlighter-rouge">dim_dates</code>. Here’s how I generate a calendar and shape it into a usable dimension (modified from a find on Stack Overflow, no shame):</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">begin_date</span> <span class="o">=</span> <span class="s">'2021-01-01'</span>
<span class="n">end_date</span>   <span class="o">=</span> <span class="s">'2030-12-31'</span>

<span class="p">(</span>
    <span class="n">spark</span><span class="p">.</span><span class="n">sql</span><span class="p">(</span>
        <span class="s">"select explode(sequence(to_date('%s'), to_date('%s'), interval 1 day)) "</span>
        <span class="s">"as calendar_date"</span> <span class="o">%</span> <span class="p">(</span><span class="n">begin_date</span><span class="p">,</span> <span class="n">end_date</span><span class="p">)</span>
    <span class="p">)</span>
    <span class="p">.</span><span class="n">createOrReplaceTempView</span><span class="p">(</span><span class="s">'dates'</span><span class="p">)</span>
<span class="p">)</span>
</code></pre></div></div>

<p>Then a SQL pass adds the calendar attributes:</p>

<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">create</span> <span class="k">or</span> <span class="k">replace</span> <span class="k">temporary</span> <span class="k">view</span> <span class="n">temp_silver_dates</span> <span class="k">as</span> <span class="p">(</span>
  <span class="k">select</span>
    <span class="n">calendar_date</span><span class="p">,</span>
    <span class="nb">year</span><span class="p">(</span><span class="n">calendar_date</span><span class="p">)</span>  <span class="k">as</span> <span class="nb">year</span><span class="p">,</span>
    <span class="k">month</span><span class="p">(</span><span class="n">calendar_date</span><span class="p">)</span> <span class="k">as</span> <span class="k">month</span><span class="p">,</span>
    <span class="k">lower</span><span class="p">(</span><span class="n">date_format</span><span class="p">(</span><span class="n">calendar_date</span><span class="p">,</span> <span class="s1">'MMMM'</span><span class="p">))</span> <span class="k">as</span> <span class="n">calendar_month</span><span class="p">,</span>
    <span class="k">day</span><span class="p">(</span><span class="n">calendar_date</span><span class="p">)</span>   <span class="k">as</span> <span class="k">day</span><span class="p">,</span>
    <span class="k">lower</span><span class="p">(</span><span class="n">date_format</span><span class="p">(</span><span class="n">calendar_date</span><span class="p">,</span> <span class="s1">'EEEE'</span><span class="p">))</span> <span class="k">as</span> <span class="n">calendar_day</span><span class="p">,</span>
    <span class="n">weekday</span><span class="p">(</span><span class="n">calendar_date</span><span class="p">)</span> <span class="o">+</span> <span class="mi">1</span> <span class="k">as</span> <span class="n">day_of_week</span><span class="p">,</span>
    <span class="k">case</span> <span class="k">when</span> <span class="n">weekday</span><span class="p">(</span><span class="n">calendar_date</span><span class="p">)</span> <span class="o">&lt;</span> <span class="mi">5</span> <span class="k">then</span> <span class="s1">'Y'</span> <span class="k">else</span> <span class="s1">'N'</span> <span class="k">end</span> <span class="k">as</span> <span class="n">is_week_day</span><span class="p">,</span>
    <span class="k">case</span> <span class="k">when</span> <span class="n">calendar_date</span> <span class="o">=</span> <span class="n">last_day</span><span class="p">(</span><span class="n">calendar_date</span><span class="p">)</span> <span class="k">then</span> <span class="s1">'Y'</span> <span class="k">else</span> <span class="s1">'N'</span> <span class="k">end</span> <span class="k">as</span> <span class="n">is_last_day_of_month</span><span class="p">,</span>
    <span class="n">dayofmonth</span><span class="p">(</span><span class="n">calendar_date</span><span class="p">)</span> <span class="k">as</span> <span class="n">day_of_month</span><span class="p">,</span>
    <span class="n">dayofyear</span><span class="p">(</span><span class="n">calendar_date</span><span class="p">)</span>  <span class="k">as</span> <span class="n">day_of_year</span><span class="p">,</span>
    <span class="n">weekofyear</span><span class="p">(</span><span class="n">calendar_date</span><span class="p">)</span> <span class="k">as</span> <span class="n">week_of_year_iso</span><span class="p">,</span>
    <span class="n">quarter</span><span class="p">(</span><span class="n">calendar_date</span><span class="p">)</span>    <span class="k">as</span> <span class="n">quarter_of_year</span>
  <span class="k">from</span> <span class="n">dates</span>
<span class="p">)</span>
</code></pre></div></div>

<p>Finally we materialise the Delta dimension, deriving week boundaries and left-joining a public-holiday table so analysts get <code class="language-plaintext highlighter-rouge">is_public_holiday</code> for free:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">spark</span><span class="p">.</span><span class="n">sql</span><span class="p">(</span><span class="sa">f</span><span class="s">'''
    create or replace table </span><span class="si">{</span><span class="n">target_catalog</span><span class="si">}</span><span class="s">.</span><span class="si">{</span><span class="n">silver_dim_date</span><span class="p">.</span><span class="n">schema</span><span class="si">}</span><span class="s">.</span><span class="si">{</span><span class="n">silver_dim_date</span><span class="p">.</span><span class="n">table</span><span class="si">}</span><span class="s">
    using delta
    select
      calendar_date, year, month, calendar_month, day, calendar_day, day_of_week,
      is_week_day, day_of_month, is_last_day_of_month, day_of_year,
      week_of_year_iso, quarter_of_year,
      date_sub(calendar_date, day_of_week - 1) as week_start,
      date_add(calendar_date, 7 - day_of_week) as week_end,
      if(h.holiday_date is null, 'n', 'y')     as is_public_holiday
    from temp_silver_dates d
    left join </span><span class="si">{</span><span class="n">target_catalog</span><span class="si">}</span><span class="s">.</span><span class="si">{</span><span class="n">silver_dim_public_holiday</span><span class="p">.</span><span class="n">schema</span><span class="si">}</span><span class="s">.</span><span class="si">{</span><span class="n">silver_dim_public_holiday</span><span class="p">.</span><span class="n">table</span><span class="si">}</span><span class="s"> h
      on d.calendar_date = h.holiday_date
'''</span><span class="p">)</span>
</code></pre></div></div>

<h3 id="gold--aggregates">Gold — aggregates</h3>

<p>Gold is the summarisation layer: grouping individual quantitative records into categorical aggregates. “What’s the total sales of all retail stores in the North in December?” — that’s an aggregate function (sum, mean, average) applied over <strong>fact</strong> data and grouped by <strong>dimension</strong> data.</p>

<p>One design decision to make consciously: <strong>view or physical table?</strong> If the data is volatile or you want the number always current, a view that computes the summarisation on read can be right; if the aggregate is expensive or point-in-time stable, a physical table that receives appends is often cheaper to serve. The temporal nature of the data decides it.</p>

<h2 id="delta-lake">Delta Lake</h2>

<p>Delta Lake is the open-source storage layer the whole thing sits on — the best one-liner for it is <em>parquet files on steroids</em>. Three features do most of the heavy lifting here (and there are many more — the Delta docs have clearer, richer examples than any single post can).</p>

<h3 id="change-data-feed-cdf">Change Data Feed (CDF)</h3>

<p>CDF is what lets each medallion tier consume incremental data efficiently off the tier below. Enable it <em>deliberately</em>, not by default — you’ll find tables where it isn’t needed, so turn it on per-table where you actually stream changes. Combined with Spark Streaming and Delta’s upsert/merge, CDF is the backbone of doing CDC entirely inside the lakehouse.</p>

<h3 id="time-travel">Time Travel</h3>

<p>Time Travel lets you read a table as of an earlier version or timestamp, with roughly a year of history retained. This is unglamorous until it saves your week: we had production customer data accidentally deleted, and because the incrementals had also mirrored the deletion into the lakehouse, we recovered <em>both</em> the production system and the Delta table from a version before the delete. It’s a safety net you won’t appreciate until you need it.</p>

<h3 id="liquid-clustering">Liquid Clustering</h3>

<p>Liquid Clustering improves on manual partitioning and Z-ORDER by simplifying layout decisions to optimise query performance — and crucially it lets you <em>redefine clustering columns without rewriting existing data</em>, so layout evolves alongside analytic needs. In practice, it removes a whole class of “go optimise your tables” chores. We were still applying it to a few multi-terabyte tables at the time of writing.</p>

<h2 id="orchestration">Orchestration</h2>

<p>The line that matters most: <strong>planning your update cadence is directly proportional to your spend on Databricks.</strong> Tight budget, low urgency? Run weekly. Fast decisions that need fresh numbers? Hourly, or every three or six hours. Cadence is a cost dial, and you should be turning it on purpose.</p>

<p>Databricks Workflows comes out of the box and is the de-facto scheduler on the platform — no separate orchestration infra to deploy or maintain. (You’ll know the alternatives: Apache Oozie, Airflow, Dagster.) The one honest caveat: orchestration reaches <em>within</em> the platform well, but ingestion still lives mostly outside it — a gap I hoped the Arcion acquisition would shrink.</p>

<p>Three things to get right when scheduling jobs:</p>

<p><strong>Compute.</strong> Three types — Serverless, Job Compute, and All-purpose. Prefer a shared <strong>Job Cluster</strong>: it cuts overall cost and ships with Photon enabled by default, so you pay less for more. For irregular, infrequent jobs, try <strong>Serverless</strong>. For <strong>All-purpose</strong> clusters, actually look at the compute metrics to find the bottleneck and tune to it.</p>

<p><strong>Number of jobs.</strong> As sources and tables multiply, job count grows, a single workflow stops being enough, and you start nesting workflows inside larger ones. That’s where cluster-driver problems surface. The easy path out is Serverless. The hands-on path is disciplined trial and error: grow the driver size, add worker nodes, or fall back from Spot to On-demand — but change <em>one thing at a time</em> so you learn which lever actually worked.</p>

<p><strong>Dependency planning.</strong> Your warehouse design dictates which jobs depend on which. Build a <strong>core workflow</strong> that cannot be allowed to fail, and keep everything less critical in separate workflows so a noisy neighbour can never break essential loading.</p>

<h2 id="why-this-is-enough">Why this is enough</h2>

<p>That’s the set — ingestion, the Bronze/Silver/Gold processing pipeline, the handful of Delta features that carry real weight, and a scheduling philosophy tied to cost. Individually none of them are exotic; together they’re more than one person needs to run a lakehouse that a whole business can depend on. The point was never to build less. It’s that with the right platform, the essentials are small enough to own — and once you’ve got them, “building a lakehouse” stops being daunting and starts being a thing you simply do.</p>]]></content><author><name>Maximilian Jackson</name></author><category term="data-engineering" /><category term="databricks" /><category term="lakehouse" /><category term="delta-lake" /><category term="etl" /><category term="medallion-architecture" /><category term="field-notes" /><summary type="html"><![CDATA[Building a lakehouse sounds like a daunting engineering task. It’s a phrase that summons images of a full platform team, months of infrastructure yak-shaving, and a budget line that makes finance wince. I wanted to write up the fundamental components I actually used to build a lakehouse on Databricks at GetGo — and along the way show that, for a single-person data operation, it’s genuinely more tractable than the marketing suggests. The reason is simple: Databricks bundles most of the hard parts out of the box, so one person can spend their time on data processing rather than infrastructure. You’ll soon see that it’s really easy. Let’s go.]]></summary></entry></feed>